
Leading Voices - Prof. Vijayan K. Asari
On October 8, 2026, the Editorial Office of Intelligence & Robotics (IR, ISSN: 2770-3541) had the honor of interviewing Prof. Vijayan K. Asari, Professor in the Department of Electrical and Computer Engineering at the University of Dayton, USA, Ohio Research Scholars Endowed Chair in Wide Area Surveillance, and Director of the Center of Excellence for Computational Intelligence and Machine Vision (Vision Lab). The interview was conducted by Assoc. Prof. Xiaofei Yang from the School of Electronics and Communication Engineering at Guangzhou University, China, and a Junior Editorial Board Member of IR.
As part of the Leading Voices in Intelligence & Robotics interview series celebrating the fifth anniversary of IR, the conversation explored advances in image processing, computer vision, and deep learning, including their applications in object detection and tracking, scene understanding, and facial recognition, as well as emerging challenges and future directions in intelligent visual perception.
Below are the details of the interview:
Questions:
Q1. The evolution of image processing and computer vision
Image processing has evolved from traditional enhancement, restoration, and feature-based methods toward increasingly learning-driven approaches. Given your long-standing work in image processing and computer vision, what do you see as the most significant changes in the field over the past decade? Do you think traditional image processing techniques still have an important role to play alongside modern deep learning methods?
Q2. Image quality and information recovery in the era of AI
Your recent work on multiwavelet-based image super-resolution for remote sensing explores how advanced feature fusion can recover and enhance visual information from low-resolution imagery. More broadly, what do you see as the fundamental challenges in image enhancement and super-resolution today? How should researchers balance perceptual quality, computational efficiency, and the fidelity of the recovered information, particularly when images are used for downstream analysis and decision-making?
Q3. From image processing to intelligent visual understanding
Your recent research spans image super-resolution, semantic segmentation of Arctic sea-ice meltponds, and histopathologic image classification. These applications require not only improving image quality but also extracting meaningful information from complex visual data. What do you see as the key challenges in moving from image processing toward deeper visual understanding? How can future vision systems better connect low-level image processing with high-level semantic interpretation?
Q4. Efficient AI for real-world visual applications
Your 2026 work on XtraLight-MedMamba explores an ultra-lightweight architecture for histopathologic image classification, while other recent projects address efficient vision models for remote sensing and surveillance. What motivates the growing emphasis on lightweight and computationally efficient AI in your research? In your view, what are the main technical challenges in achieving a better balance between model complexity, accuracy, generalization, and real-time deployment?
Q5. The future of intelligent image analysis
Looking ahead five to ten years, how do you think image processing and computer vision will evolve as AI models become increasingly capable? Which emerging directions - such as multimodal learning, generative models, efficient AI, neuromorphic vision, or domain-adaptive image analysis - do you think could have the greatest impact on the future of intelligent visual systems?
About Prof. Vijayan K. Asari:
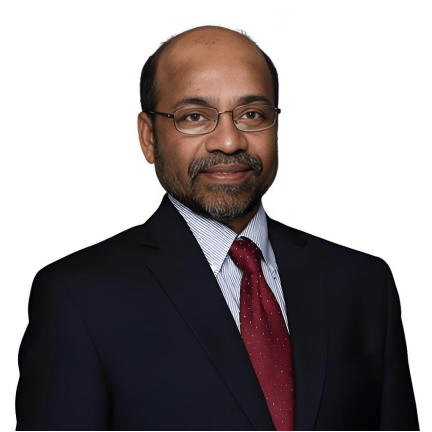
Prof. Vijayan K. Asari is a Professor in the Department of Electrical and Computer Engineering at the University of Dayton, USA, and the Ohio Research Scholars Endowed Chair in Wide Area Surveillance. He also directs the Center of Excellence for Computational Intelligence and Machine Vision (Vision Lab). His research interests include image processing, computer vision, pattern recognition, machine learning, and deep learning, with applications in wide-area surveillance, object detection and tracking, facial recognition, and scene analysis. He has authored or co-authored more than 700 research articles, including over 130 peer-reviewed journal papers, and holds several U.S. patents. He is a Fellow of SPIE and a recipient of the Fulbright Specialist designation and several awards for research and technical leadership.
About Assco. Prof. Xiaofei Yang:
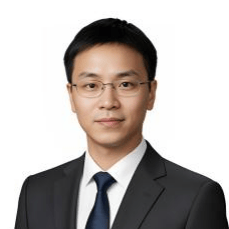
Assoc. Prof. Xiaofei Yang received the B.S. degree from Suihua University, Suihua, China, in 2011, and the M.S. and Ph.D. degrees from Harbin Institute of Technology, Harbin, China, in 2014 and 2019, respectively. From 2020 to 2023, he was a Postdoctoral Researcher with the Department of Computer and Information Science, University of Macau, Macao, China. He joined the School of Electronics and Communication Engineering, Guangzhou University, Guangzhou, China, in 2023, where he is currently an Associate Professor. His research interests include artificial intelligence, deep learning, remote sensing image interpretation, hyperspectral image analysis, geospatial intelligence, and intelligent Earth observation. Dr. Yang is a recipient of the Guangdong Provincial Young Talent Program. He has served as a reviewer for several IEEE journals.
Editor: Shine Wei
Production Editor: Xingyue Luo
Respectfully Submitted by the Editorial Office of Intelligence & Robotics