fig4
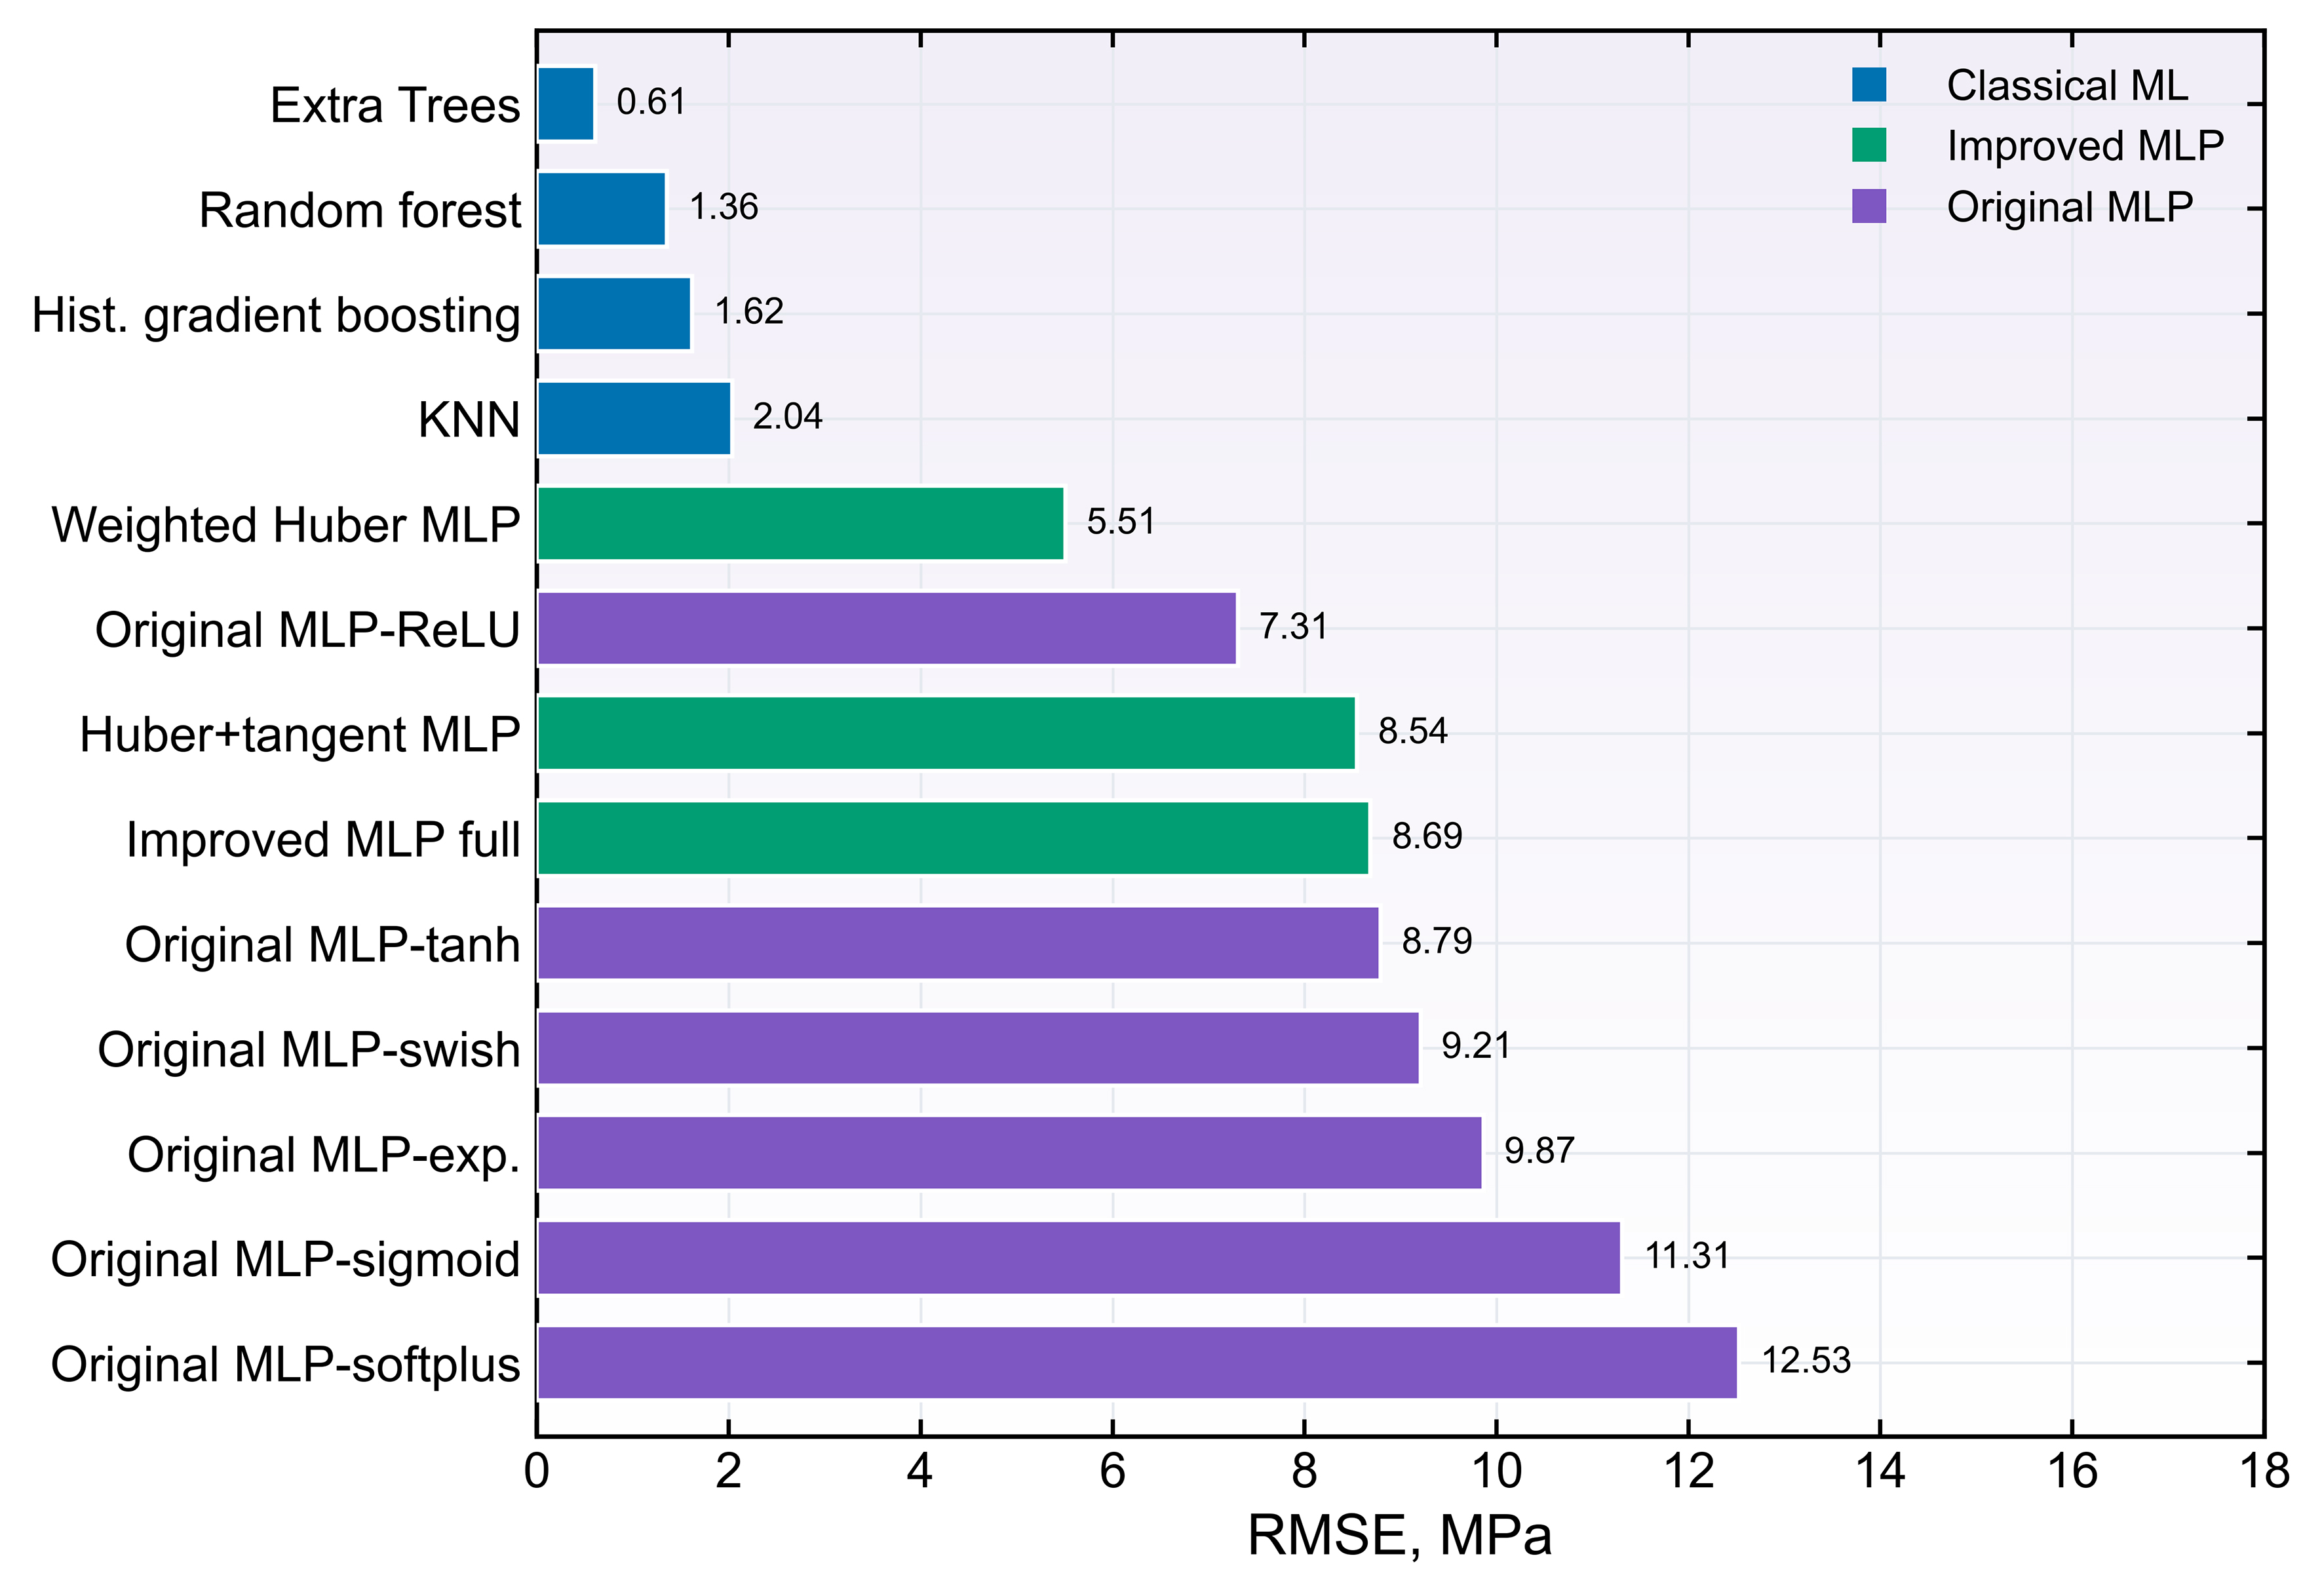
Figure 4. Preliminary performance comparison of candidate teacher algorithms and student-network configurations using an 80/20 pointwise split of the complete dataset. These results are used only for model screening and do not represent the final leave-one-temperature-out generalization performance. KNN: K-nearest neighbors; MLP: multilayer perceptron; ReLU: rectified linear unit; ML: machine learning; RMSE: root mean square error.